Artificial Intelligence

TerraZero: Procedural Driving Simulation for Zero-Demonstration Self-Play at Scale
| Source: arXiv

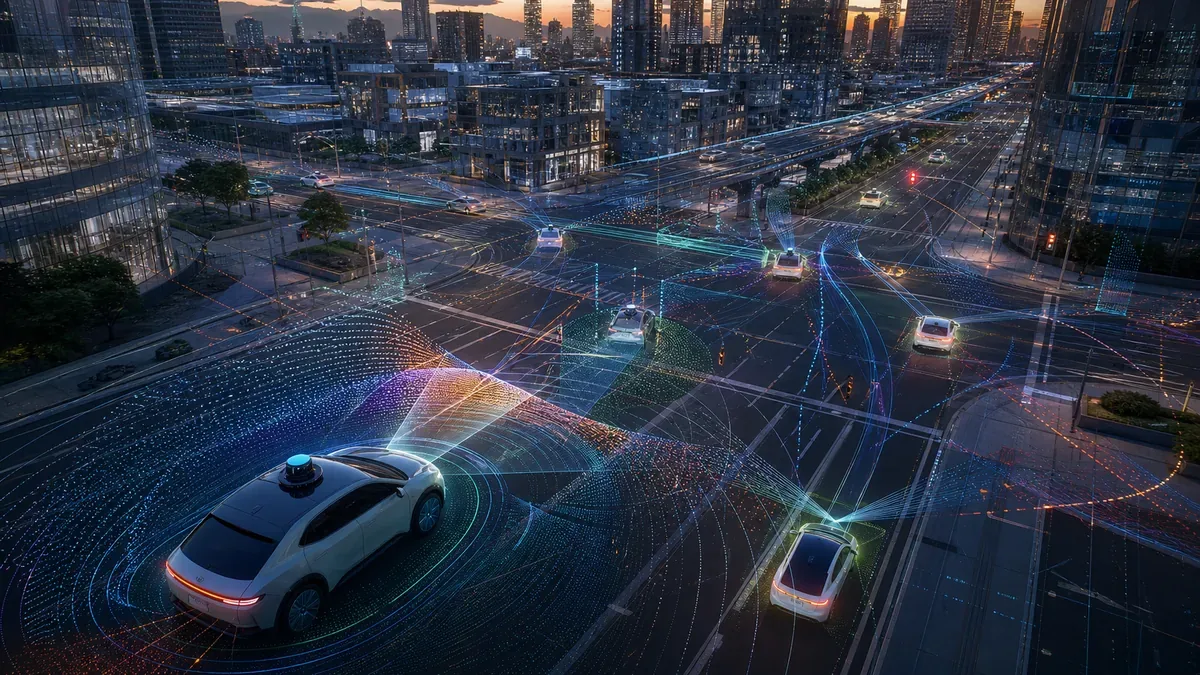
Preprint — not peer-reviewed. Training robust autonomous driving agents requires a simulator that is fast enough for reinforcement learning at scale, realistic enough to ground behavior in real-world map structure, and diverse enough to cover the safety-critical long tail that logged data rarely contains. We present TerraZero, a procedural driving simulator and self-play training stack. A configurable C engine runs simulation on the CPU and policy inference on the GPU over a zero-copy path, sustaining 1.3M agent-steps per se

Training robust autonomous driving agents requires a simulator that is fast enough for reinforcement learning at scale, realistic enough to ground behavior in real-world map structure, and diverse enough to cover the safety-critical long tail that logged data rarely contains. We present TerraZero, a procedural driving simulator and self-play training stack. A configurable C engine runs simulation on the CPU and policy inference on the GPU over a zero-copy path, sustaining 1.3M agent-steps per second on a single server-grade GPU, far faster than existing object-level simulators, while keeping fidelity lighter single-agent systems omit: heterogeneous agents, multiple dynamics models, and full traffic-rule enforcement. TerraZero treats logged data only as a source of real-world map geometry, populating each map with randomized rule-based road users and signal controllers and randomizing agent dynamics, rewards, and sizes per episode, so a map yields an unbounded set of scenarios. Every reported policy trains from scratch by reinforcement learning alone on a compute-efficient self-play recipe across GPUs, with zero human demonstrations and no fallback planner at inference. Policies generalize zero-shot across cities and datasets, including emergent left-hand-traffic driving without explicit supervision. As an ego policy, TerraZero is the first fully learned policy to top the InterPlan long-tail benchmark, ahead of larger learned planners; on routine-driving val14 it ranks among the best approaches and is the safest, posting the best collision and time-to-collision scores. On Waymo Open Sim Agents realism the same recipe outperforms other demonstration-free methods and is competitive with the strongest reference-anchored self-play method. One stack serves both roles: driving policies across dynamics for cars and trucks, and sim agents that jointly control vehicles, pedestrians, and cyclists.
Read the original source →

Related Stories

Artificial Intelligence

Integrating cooperative breeding with reciprocity and culture extends Hamilton's rule to humans.

We study how kinship and reciprocity shape giving and child care support in societies with limited access to markets. Extending Hamilton's rule to incorporate reciprocity, we test it using behavioral data from dictator games and surveys in remote matrilocal and patrilocal villages of northeast India (N = 406 parents of young children). We replicate with data from urban Manila neighborhoods (N = 301) and the Solomon Islands (N = 624). Consistent with predictions, transfers to recipients increase

Continue reading
Artificial Intelligence

Multi-omics atlas of chronic exercise.

Exercise reduces all-cause mortality, yet its molecular effects across organs, sexes, and circadian phases remain incompletely understood. We subjected mice to 8 weeks of voluntary wheel running and collected 22 tissues and plasma during active and inactive phases for bulk RNA sequencing, metabolomics, proteomics, and single-nucleus RNA and methylation sequencing. Exercise induced canonical fiber-type switching and widespread, tissue-specific remodeling, with the largest transcriptomic changes i

Continue reading
Artificial Intelligence

A microexon regulatory code reveals autism-linked genetic variation.

Neuronal microexons are a highly conserved class of alternative splicing events enriched in genes with critical functions in nervous system biology 1,2 . Microexon splicing is often disrupted in the brains of autistic individuals, and mice with microexon deficiencies display autism-like phenotypes 1,3,4 . However, the full landscape of microexons is not known, and the impact of genetic variation on these exons has not been systematically investigated. Here, through extensive transcriptome profil

Continue reading
Artificial Intelligence

Deep learning of fossil pollen morphology reveals 25,000 y of ecological change in eastern African grasslands.

Grass (Poaceae) pollen is largely overlooked in investigations of grassland evolution because the pollen of most species cannot be differentiated using traditional optical microscopy. However, the combination of superresolution microscopy and deep learning enables the capture and quantification of distinct morphological variation across the pollen of grass species. Using a semisupervised deep-learning strategy, we trained convolutional neural networks (CNNs) on superresolution images of known mo

Continue reading
Artificial Intelligence

Tyrosine phosphorylation unfolds nucleophosmin and disrupts its integration into the nucleolus.

Nucleophosmin (NPM1) is a multifunctional nucleolar protein essential for ribosome biogenesis, genome stability, and stress responses. Its integration into the nucleolus depends on its oligomerization and multivalent interactions that enable liquid-liquid phase separation (LLPS). Here, we investigate how tyrosine phosphorylation at Tyr17, Tyr29, and Tyr67 located within the interface between monomers at the N-terminal oligomerization domain regulates NPM1 structure and function. Replacing tyrosi

Continue reading