Artificial Intelligence

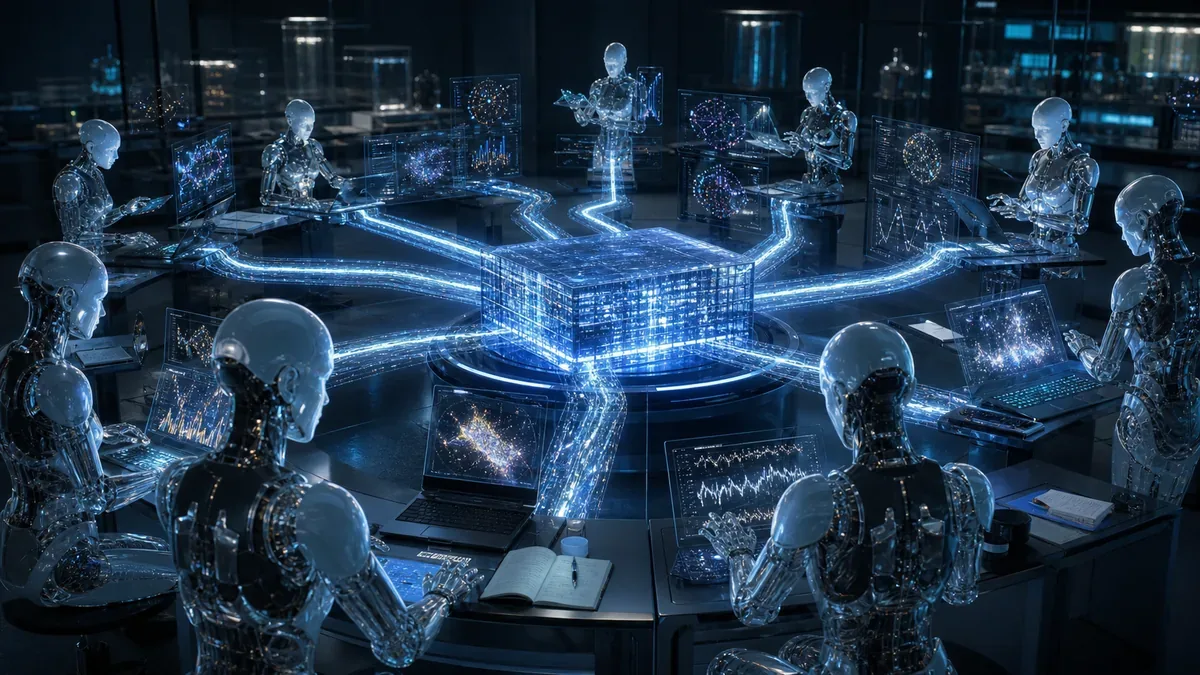
Many AI analysts, one dataset: Navigating the agentic data science multiverse.
| Source: Proceedings of the National Academy of Sciences of the United States of America

Empirical conclusions depend not only on data but also on analytic decisions. Many-analyst studies have quantified this dependence: independent teams testing the same hypothesis on the same dataset regularly reach conflicting conclusions. But such studies require costly human coordination. We show that fully autonomous AI analysts built on large language models (LLMs) can, cheaply and at scale, produce the analytic dispersion observed in human many-analyst studies. In our framework, each AI anal

Empirical conclusions depend not only on data but also on analytic decisions. Many-analyst studies have quantified this dependence: independent teams testing the same hypothesis on the same dataset regularly reach conflicting conclusions. But such studies require costly human coordination. We show that fully autonomous AI analysts built on large language models (LLMs) can, cheaply and at scale, produce the analytic dispersion observed in human many-analyst studies. In our framework, each AI analyst independently executes a complete analysis pipeline on a fixed dataset and hypothesis; a separate AI auditor screens every run for methodological validity. Across three datasets, AI analyst-produced analyses exhibit substantial dispersion in effect sizes, [Formula: see text]-values, and conclusions. This dispersion can be traced to identifiable analytic choices in preprocessing, model specification, and inference that vary systematically across LLM and persona conditions. Critically, the outcomes are steerable: reassigning the analyst persona or LLM shifts the distribution of results even among methodologically sound runs. These results highlight a central challenge for AI-automated empirical science: when defensible analyses are cheap to generate, evidence becomes abundant and vulnerable to selective reporting. The same capability also helps address it: treating analyst results as distributions makes analytic uncertainty visible, and deploying AI analysts against a published specification can reveal how much disagreement stems from underspecified design choices. Taken together, our results motivate a transparency norm: AI-generated analyses should be accompanied by multiverse-style reporting and full disclosure of the prompts used, on par with code and data.
Read the original source →

Related Stories

Artificial Intelligence

Plant fiber exploitation contributed to the emergence of ground-edged cutting tools in North China.

Ground-edged cutting tools are widely regarded as technological hallmarks of early agriculture in North China, commonly hypothesized to have been developed primarily for cereal harvesting. Yet the functional foundations of this innovation remain insufficiently tested. This study integrates use-wear and microfossil analyses of 140 stone tools from the Peiligang site, with experimental data, to reassess their roles within long-term trajectories of technological change from the Late Paleolithic to

Continue reading
Artificial Intelligence

Neural network-augmented Pfaffian wave-functions for scalable simulations of interacting fermions.

Developing accurate numerical methods for strongly interacting fermions is crucial for improving our understanding of various quantum many-body phenomena, especially unconventional superconductivity. Recently, neural quantum states have emerged as a promising approach for studying correlated fermions, highlighted by the hidden fermion and backflow methods, which use neural networks to model corrections to fermionic quasiparticle orbitals. In this work, we expand these ideas to the space of Pfaff

Continue reading
Artificial Intelligence

Why friends in common reveal network stars.

The Friendship Paradox states that, on average, your friends have more friends than you do. We extend this to common friends-those who appear in multiple people's friend lists. We show that the more people who share a common friend, the more connected that person tends to be, and we derive an expression quantifying this progression. In a regional Facebook network, a common friend to three randomly sampled individuals has on average more friends than 99.9% of the network. In a citation network, a

Continue reading
Artificial Intelligence

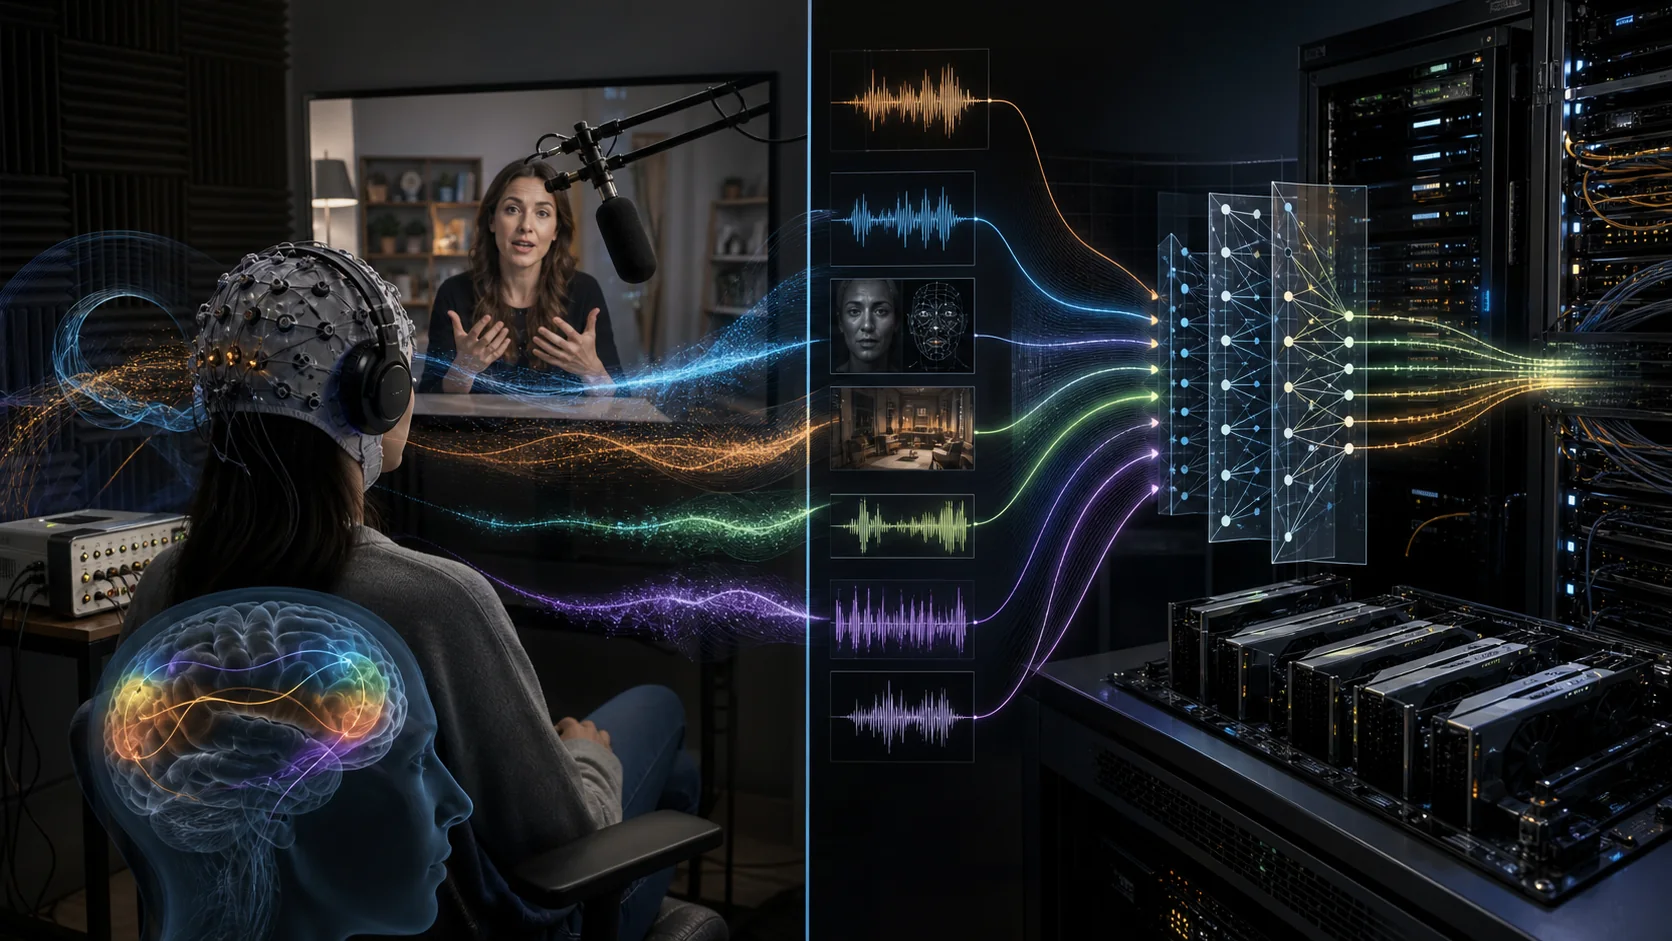
Sensory context improves language prediction in humans and LLMs.

Language is a fundamental human capacity. Large language models (LLMs) have presented the first viable model of language outside of humans, yet how these models learn and use language differs significantly from humans. Here, we compare LLMs and humans predicting language with varying levels of sensory information-from disembodied written text to audiovisual videos of speakers-to demonstrate that, in both humans and LLMs, sensory context is critical for optimal performance. We asked human partici

Continue reading
Artificial Intelligence

Treatment Decisions in Multiple Myeloma.

Revolutions in transplantation and targeted and immune therapies have transformed multiple myeloma from a disease with an associated survival of a few years into one for which functional cure is an emerging goal. This abundance of effective therapies has created clinical complexity. Here we provide a practical framework, anchored in trial evidence and informed by emerging biologic discoveries, for the navigation of treatment decisions across the disease spectrum. We outline how cytogenetic and g

Continue reading